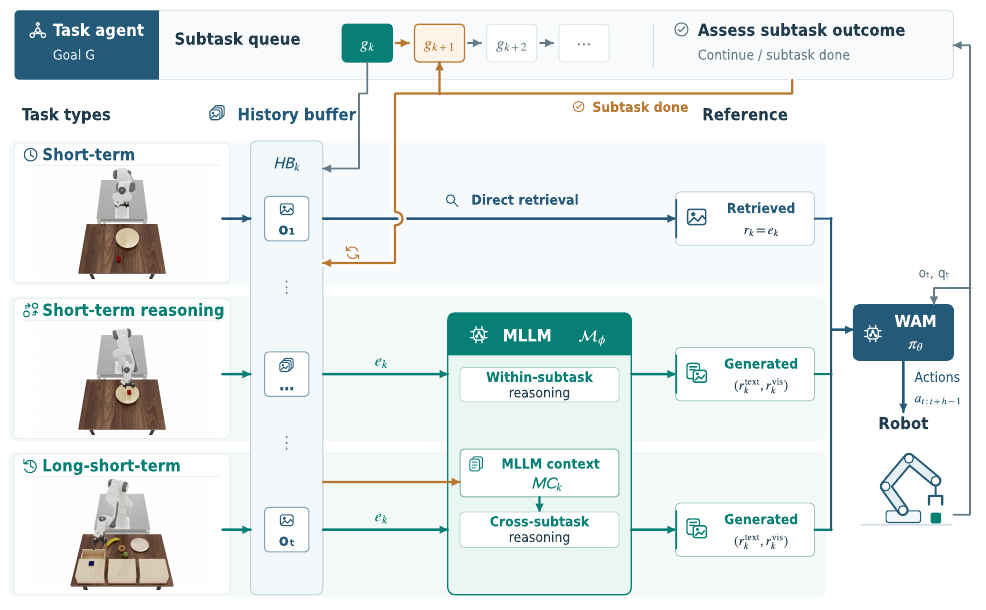
TL;DR: GEMA turns a robot's past observations into task-specific guidance: a multimodal language model, acting as a memory foundation model, interprets what the robot saw to generate text-and-image references (or reuses a retrieved observation directly), which a world action model executes while a task agent picks subtasks and checks progress. On three memory-dependent manipulation tasks it averages 81.0% success, 12 points above the strongest memory-augmented baseline.