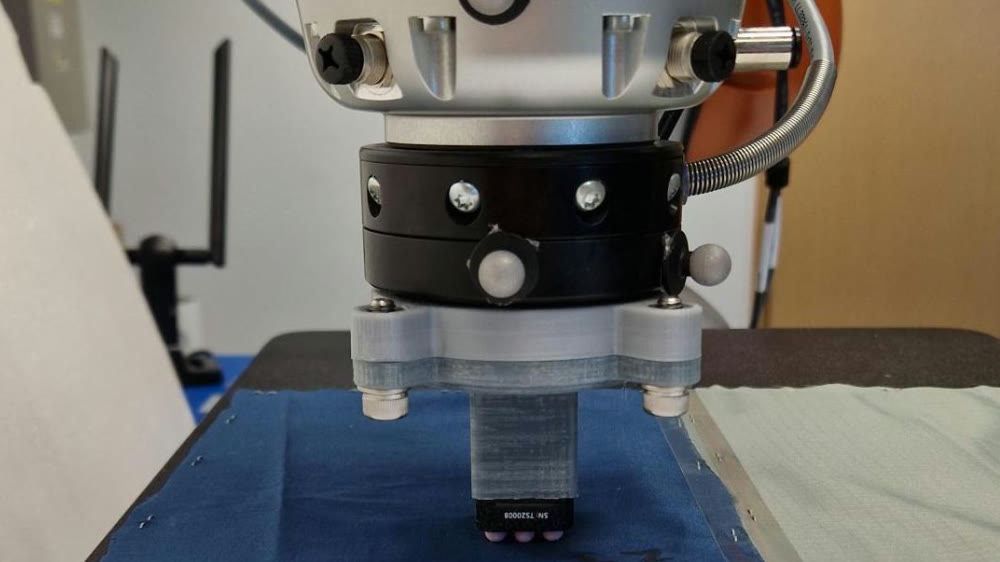
TL;DR: This paper explores the use of vision foundational models and pre-trained representations to enhance tactile representation learning and multi-modal continual learning.
TL;DR: This paper explores the use of vision foundational models and pre-trained representations to enhance tactile representation learning and multi-modal continual learning.